Expected May 2027
M.S. in Business Analytics
Wake Forest University · School of Business
Relevant coursework: Python, Statistics.
Business analytics candidate with a health science degree and commercial experience at Johnson & Johnson MedTech and SPX FLOW
I came to analytics from health science, by way of marketing and commercial roles at Johnson & Johnson MedTech and SPX FLOW in Shanghai. I use statistics, Python and Excel to answer business questions and explain the answer clearly to the people who have to act on it. What interests me most is the point where a model meets a decision, where the number becomes a budget, a forecast or a patient outcome.
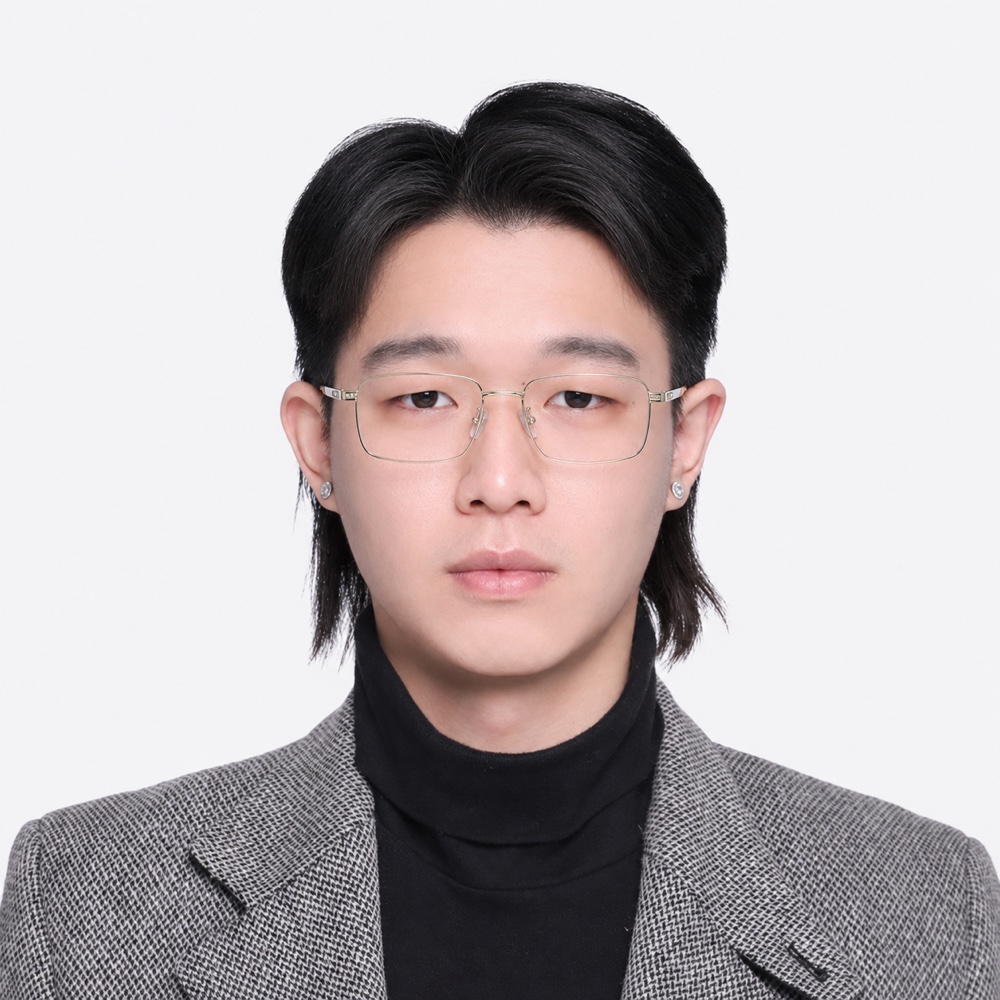
I'm pursuing my M.S. in Business Analytics at Wake Forest, and I'm targeting analytics roles in healthcare and pharmaceuticals — with a secondary interest in financial services, where the modeling problems are structurally similar.
That focus isn't arbitrary. My undergraduate degree is in Health and Exercise Science, also at Wake Forest, so I read clinical and physiological data as a native language rather than as an unfamiliar domain. Both of my internships were commercial roles inside health organizations: marketing at Ethicon, part of Johnson & Johnson MedTech, and commercial work at SPX FLOW's health and nutrition business, both in Shanghai.
What those roles taught me is that the constraint in a commercial healthcare team is rarely the analysis. It's the translation. I spent two summers turning technical capability into something a client would act on, and I'm now building the quantitative half so I can do both ends of that conversation myself.
Roles: I'm deliberately broad here — I'm interested in any position where analysis feeds a real commercial decision. That covers analytics and business intelligence, commercial and market-facing strategy, and operations. At this stage the quality of the problem and the people I'd learn from matter more to me than the title on the posting.
Industries: Pharmaceuticals and medical devices first; healthcare providers and payers second; banking and financial services as an adjacent fit.
Timing: Available full-time from May 2027.
Also brings: Fluent English and Mandarin, intermediate German, two summers working across U.S. and China teams, and everyday fluency with AI tools. U.S. permanent resident, authorized to work in the U.S. without sponsorship.
Each project states its context, my specific contribution, and what came out of it.
Click a project to expand it.
A retail bank began paying a $200 bonus for opening a new account. Applications grew four- to five-fold, and fraud came with them: people opening many accounts to collect the bonus repeatedly, and accounts opened under synthetic or stolen identities. The bank has to decide, at the moment an application is submitted, which ones to send to manual review. Both mistakes cost money. A missed fraud costs about $555 in bonus, onboarding and investigation time; sending a legitimate applicant to review costs about $80 in reviewer time and lost customers.
This is a five-person team project. Each of us first wrote an individual specification of predictors to build. Mine proposed features under four hypotheses: fraud rings reuse devices, emails and referral codes; scripted applications behave differently from people; fraud follows the incentive; and fake identities contain details that don't fit together. Five of the predictors in the team's final model trace to my specification, including the disposable-email flag, one of its strongest drivers. I then worked with the team on the model build, the cost analysis and the written recommendation.
Combined application, device, email, referral and marketing records and built about 50 candidate predictors, each using only information that existed before the application was submitted, so nothing from later investigations leaks into the score. Trained a logistic regression on January 2025 to July 2026 (174,448 applications) and tested it on August 2026 (37,544 applications), a later month the model never saw. Screening, stepwise selection and a multicollinearity check reduced the candidates to 20. The review threshold was set by pricing both kinds of error and choosing the cut-off with the lowest total cost, not by a statistical rule of thumb.
On the unseen month the model scored an AUC of 0.88 (how well it ranks fraud above legitimate applications; 0.5 is chance), against 0.61 for the bank's existing score. Reviewing the 11.5% of applications above the chosen threshold catches 64% of confirmed fraud and leaves 92% of legitimate applicants untouched. Estimated monthly cost of fraud plus review falls from $1.24M with no model to $0.67M, and the flagged volume fits within the review team's existing capacity.
Fraud is concentrated, so precision beats tightening on everyone. The riskiest 5% of applications by our score contain 35.5% of all confirmed fraud. The same 5% by the bank's existing score contain 4.4%, slightly worse than picking applications at random. The signals that matter are about connections and behaviour: repeat applications from the same person, devices shared across applicants, disposable email domains and unusual session speed. Salary and credit-file measures showed no signal at all.
The model is weaker on fraud that looks normal on the application: it catches roughly three-quarters of bonus abuse but under half of stolen-identity cases. Fraud labels for the most recent months were also still maturing when this was scored, so these figures will be restated as investigations close. Still in progress: testing tree-based models against this baseline, adding links between applications, and turning the result into a recommendation for the bank's risk committee.
Our practicum team is doing a semester-long analytics project for an outside client. A general AI chat tool was not enough for that. It forgets everything between sessions, each teammate gets a different answer, and nobody can tell what it checked. We needed something closer to a junior analyst on the team: one that knows the project, follows the same steps every time, and never acts on its own.
I designed and built it. I wrote the agent's rules and its nineteen procedures in plain English, decided what it may do freely and what needs approval, and directed Claude Code to write the Python tooling, which I reviewed and tested. I also set up the shared database, the scheduled reminders, and an onboarding step so a teammate can install everything by typing “set me up.”
Adanis runs on Claude Code. A rules file is read at the start of every session, and each procedure (confirm the problem, research, verify, recommend, review a deliverable, prepare for a client meeting, and so on) loads when a teammate uses its trigger phrase. Python tools handle the analytics and record keeping. A hosted PostgreSQL database holds the team's decisions, research, limits and deadlines, so what one person tells it on Monday is known on every laptop on Tuesday. Two scheduled jobs post deadline reminders and a Monday summary to the team's chat.
It can research freely, but every change to a file, code, data or a model waits for approval of that specific change. It never types a password or signs in anywhere. It never contacts the client: it drafts only when asked, and a teammate reviews and sends. It refuses to calculate a metric until the team has written down what that metric means, and it will not load client data until the data-use terms are agreed.
Getting an AI to produce an answer is easy. The work was deciding how the team could trust one. So Adanis restates every request and waits for a yes before starting, re-checks each result a second way and says what it could not check, and traces every number in a deliverable back to its source before anything leaves the team. It also keeps a log of every time it pushed back on us, and whether it turned out to be right, overruled or wrong, so that at the end of the semester we can judge the agent on evidence and decide whether to redesign it.
Adanis is up and running. Today the team uses it mainly for four things: drafting emails for a teammate to review and send, taking notes during meetings and summarizing the decisions and action items afterwards, keeping track of deadlines, and posting a Monday digest of what was recorded and what is still open. The data analysis features are built and tested but not yet in use; they come into play once the project's data is available. A hosted version that the team can reach directly from chat is planned as a second phase.
Salary is the single largest constraint a front office manages, and the league's pay structure is famously top-heavy. We asked a plain question — which performance measures actually move a player's salary — and treated it the way a commercial team would treat a pricing problem.
I carried the analysis end to end — cleaning and consolidating the raw export, engineering the two advanced measures, testing the distributional assumptions, running the hypothesis tests and confidence intervals, and building the regression through backward elimination. I also wrote the commentary documenting the reasoning at each stage. This was a team assignment and the interpretation was worked through together; my teammates pushed back on conclusions and that scrutiny made the final model better, particularly the decision to drop effective field goal percentage.
Cleaned the raw export down to twelve core box-score fields and engineered two advanced measures — effective field goal percentage and assist-to-turnover ratio. Tested distributional assumptions, ran one-sample t-tests and confidence intervals, then built a multiple regression and reduced it by backward elimination across nine successive models.
A two-variable model — age and total points — explaining 50.2% of salary variance across all 513 players (F = 257.6). Each additional year of age predicted +$633,654; each additional point scored predicted +$13,308.
Effective field goal percentage was a statistically significant predictor, and I removed it anyway. Its coefficient was strongly negative — the model was claiming that better shooters earn less, which is nonsense. The cause was sample size: players with almost no minutes attempt almost no shots, so a handful of makes produces an inflated percentage. Keeping a significant-but-senseless predictor would have made the model look stronger on paper and worse in practice. The final model kept only the two variables that were both statistically and practically defensible, and R² held near 0.50 the entire way down.
Of eight continuous variables, only age was near-symmetric enough to justify a normal approximation. Asked how often a player earns more than $10 million, the normal model returned 37.1% against an empirical 22.2%. A front office sizing a free-agent budget off the normal figure would have planned for eight-figure competition on roughly two-thirds more targets than actually existed — and over-reserved cap space accordingly.
Mean salary of $7,027,351 tested against a claimed $6M: rejected at α = 0.05 (t = 2.571, df = 512, one-tailed p = 0.005). But the scouting benchmark of 500 points survived (t = −1.613, p = 0.107) — the shortfall sat inside ordinary sampling variation. The 95% interval on mean salary, scaled to a 15-man roster, spans $93.6M to $117.2M: a $23.5M planning band.
I returned to the same question in Python as part of a three-person team, this time letting the data choose the model. We held out a quarter of the players (384 to train, 129 to test), screened eleven candidate predictors, and ran forward, backward and stepwise selection with 10-fold cross-validation. All three methods chose the same model, and it predicted the held-out salaries slightly better than a model using all eleven predictors (test error of about $6.9M; adjusted R² of 0.53). Points and age came through again at nearly the same values: about $14,000 per point scored and $626,000 per year of age. The algorithm also kept effective field goal percentage, the variable I had removed by judgment in Excel. It was only marginally significant and still pointed the wrong way, so our recommendation matched the earlier call: treat points and age as the drivers, and do not read the shooting result as a market penalty for efficiency.
The full analysis — every workbook, plus a dated decision log recording the analytical choices behind each stage — is maintained in a version-controlled repository, in the same way an analytics team would document work for review.
Projects from the fall and spring coursework will be added here as they're completed, each with the same structure: context, my specific contribution, and measurable outcome. Coursework with Dr. Nenova and Dr. Kim is expected to produce portfolio-ready analytics work this year.
Things I build outside coursework because I want them to exist. They also show how I put AI to work: I set the goal, the rules and the standard for “correct,” and an AI coding assistant writes the code.
It answers four questions for any of 491 players at 51 PGA Tour courses: what score to expect, the chance of posting the day’s low round, the chance of making the cut, and the chance of winning once the cut is made. Visitors can change the weather, wind speed and wind direction and watch the forecast move.
The predicted score is course difficulty plus a weather effect plus player skill. Skill is measured in strokes against the field, with recent rounds weighted more heavily. A simulation then adds realistic round-to-round luck for every player in the field and replays the event 10,000 times to turn scores into probabilities.
I held back the entire 2026 season and predicted it using only earlier results. Players the model gave a 60 to 80% chance of making the cut made it 69% of the time against a forecast of 67%, and cut forecasts beat a naive guess by 10%. I also publish the limits: one round of golf is mostly luck, and the page says so.
Every idea had to earn its place in testing. Adding three more tours improved accuracy, so it stayed. Adding older seasons made course predictions worse, so it came out. The data showed no reliable sign that individual players handle wind better, so I left that out and said so on the page. Knowing what to reject matters as much as knowing what to build.
It turns scores into a single, comparable number. A visitor sees their handicap, the rounds that drove it, a “top X%” ranking with a chart of where golfers sit, and how many strokes they would receive on a course of their choice.
Each round is adjusted for how hard the course was, so a 90 on a tough course counts for more than a 90 on an easy one. The handicap is the average of the best rounds, following the official World Handicap System. The ranking places that number on the USGA’s published spread of handicaps.
My first test gave a result that made no sense: a round at a short local course implied I would score almost as well at Pebble Beach. I traced it to a course difficulty figure that booking sites had listed wrongly. The formula was right and the input was not. Checking whether an answer is plausible before trusting it is a habit I bring to every analysis.
It shows the other half of analytics work: taking an official method, implementing it faithfully, and presenting the result so a non-expert understands it at a glance. The page states plainly what it leaves out and that the number is an estimate.
You bet, play your hand and get immediate feedback: whether the move was the best one, what each option was worth on average, and what a mistake cost in chips. It tracks accuracy over a session, keeps a list of recent mistakes, and produces a full strategy chart for whichever table rules you choose, with the casino-standard eight-deck shoe as the default.
I am not a software engineer, and this project did not need me to be one. I briefed the AI assistant the way I would brief an analyst: what the product should do, which casino rules to follow, and what users should see. Then I tested the result myself and sent it back for changes, including a layout rework so the whole game fits on one screen.
A strategy coach that gives wrong advice is worse than none. Before publishing, the solver was checked two ways: its strategy chart against published basic strategy, and a 3-million-hand simulation of perfect play, which returned a house edge of about 0.5%, in line with the known figure for these rules.
AI makes building fast. The part that still takes judgment is deciding what to build, defining what “correct” means and insisting on evidence before trusting the output. That is the same discipline I apply to a model or a dashboard, and it is how I expect to use AI in an analytics role.
Three things I pay attention to in healthcare, pharma, and financial services — and why the NBA project above is more relevant to them than it first appears.
In both of my internships, positioning decisions were made from experience and customer conversation. That is steadily being replaced by demands for evidence — market access and payer negotiations in particular now turn on defensible quantitative cases. The people who can hold both halves of that conversation are the ones commercial teams are short of.
Healthcare cost data, drug revenue, and financial returns share a shape: heavily right-skewed, with the decisions that matter living in the tail. My own analysis produced a clean demonstration — a normal approximation overstated a tail probability by two-thirds. The same error in a cost forecast or a risk model is not an academic problem; it is a mispriced reserve.
Software will fit a regression. What it will not do is notice that a significant coefficient implies something absurd about the world and remove it anyway. Domain knowledge is what turns a fitted model into a trustworthy one — and a health science degree plus two summers inside pharma commercial teams is precisely the domain knowledge these industries are hiring for.
Relevant coursework: Python, Statistics.
Relevant coursework: Calculus I–III, Statistics in Health Science, Economics, Public Health, Health Psychology.
Readable on screen below, and downloadable as a PDF.
Phones can't preview PDFs inline, so open it full screen instead.
Open to conversations about analytics roles in healthcare, pharmaceuticals, and financial services.